“The Sell Sider” is a column written by the sell side of the digital media community.
Today’s column is written by Ameet Shah, senior director of global technology, publisher and data strategy at Prohaska Consulting.
It’s October, five months after the General Data Protection Regulation (GDPR) went into effect, and we – well, most of us – survived. We are now living in a post-GDPR, pre-CCPA (California Consumer Privacy Act) world.
While there were certainly impacts to mainly EU- and US-based publishers, such as temporary revenue declines and data infrastructure changes, virtually all made it through this first wave. It has been a significant journey leading up to GDPR, but the data collection and utilization changes are just beginning. Welcome to the new normal.
Can publishers survive in a future model where all data used across all global media channels may be completely deterministic and gathered solely via opted-in users?
Unfair position for the Big Three (or Four)?
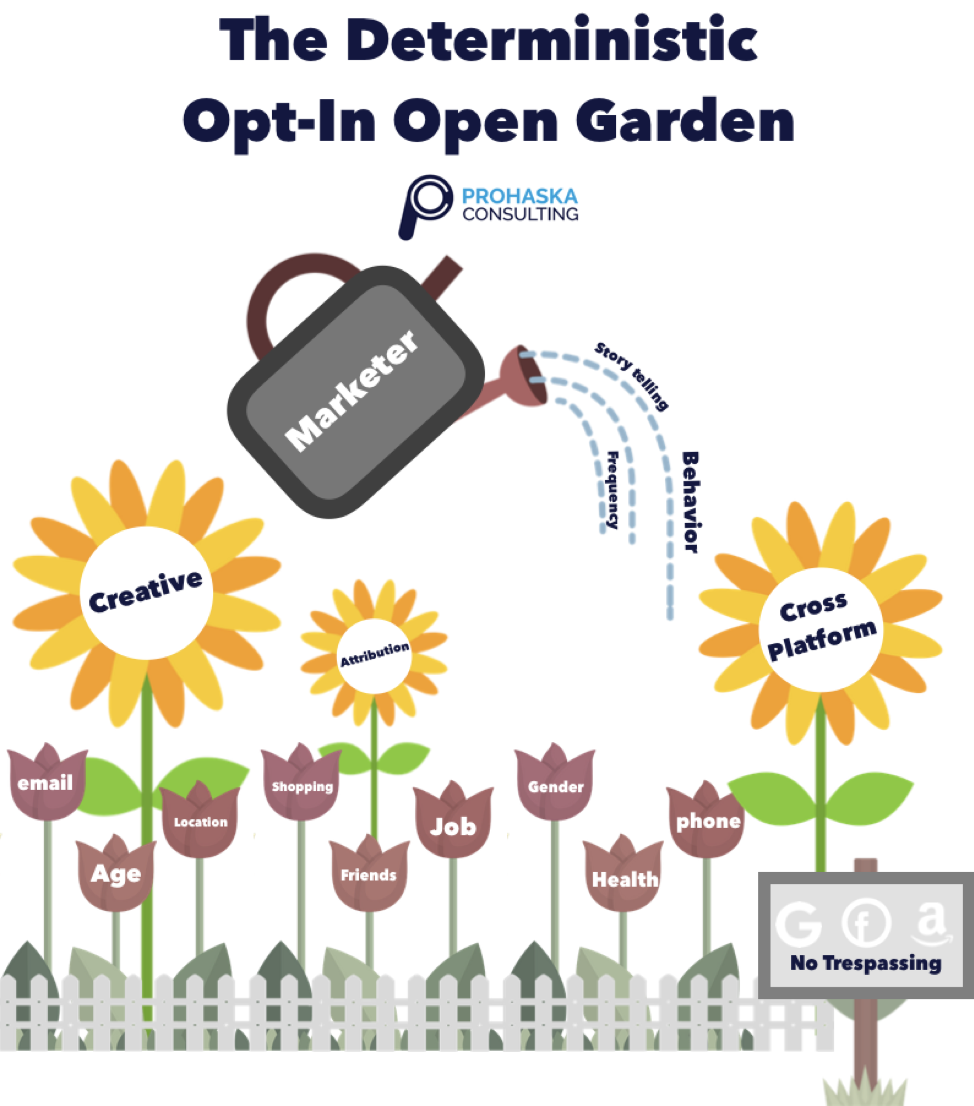
When consumer consent (opt-in) is required, scale becomes critical, cross-platform capabilities essential and audience registration and behavior collection mere table stakes. Today, this gives Google, Facebook, and Amazon a highly unfair advantage.
These companies, by the nature of their products and services, require authenticated first-party data identification (usually across platforms), user opt-in and a massive amount of high-frequency user interaction. As such, the Big Three easily and natively operate a deterministic business model with unmatched scale today.

China’s triopoly BAT – Baidu, Alibaba and Tencent – and potentially AT&T’s/Xandr’s upcoming offering might be able to match the Big Three’s scale.
They can each operate efficiently and effectively to build their own proprietary audience identity graphs and attribution modeling, while keeping the data in-house. These walled-garden environments will continue to thrive because marketers have not provided the economic incentive to force the publishers and platforms to change anything. It’s possible that data regulations and the walled gardens’ own internal privacy challenges will end up hindering them.
This is an unfair advantage to virtually every other publisher, across all media.
Why is it hard for publishers to obtain deterministic first-party data?
Publishers face a steep uphill battle. Most have no direct relationships with readers. Some have email addresses from newsletters, but that is a small subset; most visitors to their websites are random.
While the value of deterministic data has always been recognized, it typically occurs at such a small scale that many use modeling to produce probabilistic-based attributes. Recent industry consolidations and partnerships, including the recently announced LiveRamp and Drawbridge partnership, reinforce existing data pressures.
A few years ago, about 30% of data available for use in digital advertising was deterministic. Given user data privacy concerns, the increase in ad blocking and loss in user trust due to data-sharing fails, such as Cambridge Analytica, the volume has decreased to less than 10%. This is just the starting point of the ideal deterministic dataset. Once the data is gathered strictly from user opt-in, this will fall to 1%.
That does not translate to an effective, data-focused business.
What is a publisher to do?
There is always the opportunity to establish a strategic relationship with the Big Three. However, they aren’t interested in that nor do they need it. Not to mention, working with the Big Three actually helps them in the long term, as they now have the ability to add partner data to theirs, resulting in the big getting bigger.
Publishers need to be able to compete fairly. Can publishers outside of the top 10 do it alone? It’s not likely, unless they change their user interfaces and require registration for access to their content, which is not hard to gain anymore. Publishers desperately need scale and identity. Publishers without scale and identity will need partnerships.
Second-party partnerships are critical since they might be the only way deterministic data will be available at any meaningful scale. These arrangements might include industry partnerships; advertiser, vertical or horizontal partnerships; data exchanges; or other unique combinations. Essential scale will follow.
But that’s just one side of the equation. From there, publishers need to develop or connect to first-party ID graphs. Users need to be connected to all of their devices and locations, and geo-based data collection is essential for establishing these links. This requires log-level data capture to build the graph, which needs to be combined with partners’ data to establish scale and accuracy.
German publishers are trying a more aggressive approach. They are uniting in a last-ditch effort to combat Google and Facebook with a shared, unified login. Consortiums have been tried in the United States, but there are many complexities, including hypercompetition, privacy and monetization. So, what works in Germany might not in the United States right now, but could under better or more necessary circumstances.
From there, audience-based targeting, attribution, personalization and marketing become much more effective.
Time to act
For publishers to compete effectively in our audience-based targeting environment, the time for action is now. These solutions – customer data platforms, ID graphs, data collection and partnerships – take a while to develop.
If publishers take no action now, it will hinder revenue further over the next one to two years. Taking steps now is critical to maintaining and increasing effectiveness. Without action and collaboration, the Big Three get even bigger.
In an ideal state – a healthy ecosystem and fair compensation for publishers’ efforts in content, services and audience attention – all publishers will get a bigger share of media spend. The clock is ticking; action needs to be taken immediately to develop publisher’s data-focused revenues.
Follow Prohaska Consulting (@TeamProhaska) and AdExchanger (@adexchanger) on Twitter.